
October 20, 2026
A tokenizer-free multilingual TTS model based on MiniCPM-4, supporting voice design and voice cloning.
Apache-2.0
 1 / 5
Product facts
- Type
- Web App / SaaS
- Category
- AI & Machine Learning › Voice AI (TTS / STT)
- Pricing
- Open source
- License
- Apache-2.0
- Launched
- Oct 20, 2026
- Listed
- Oct 20, 2026
- Website
- github.com
Overview
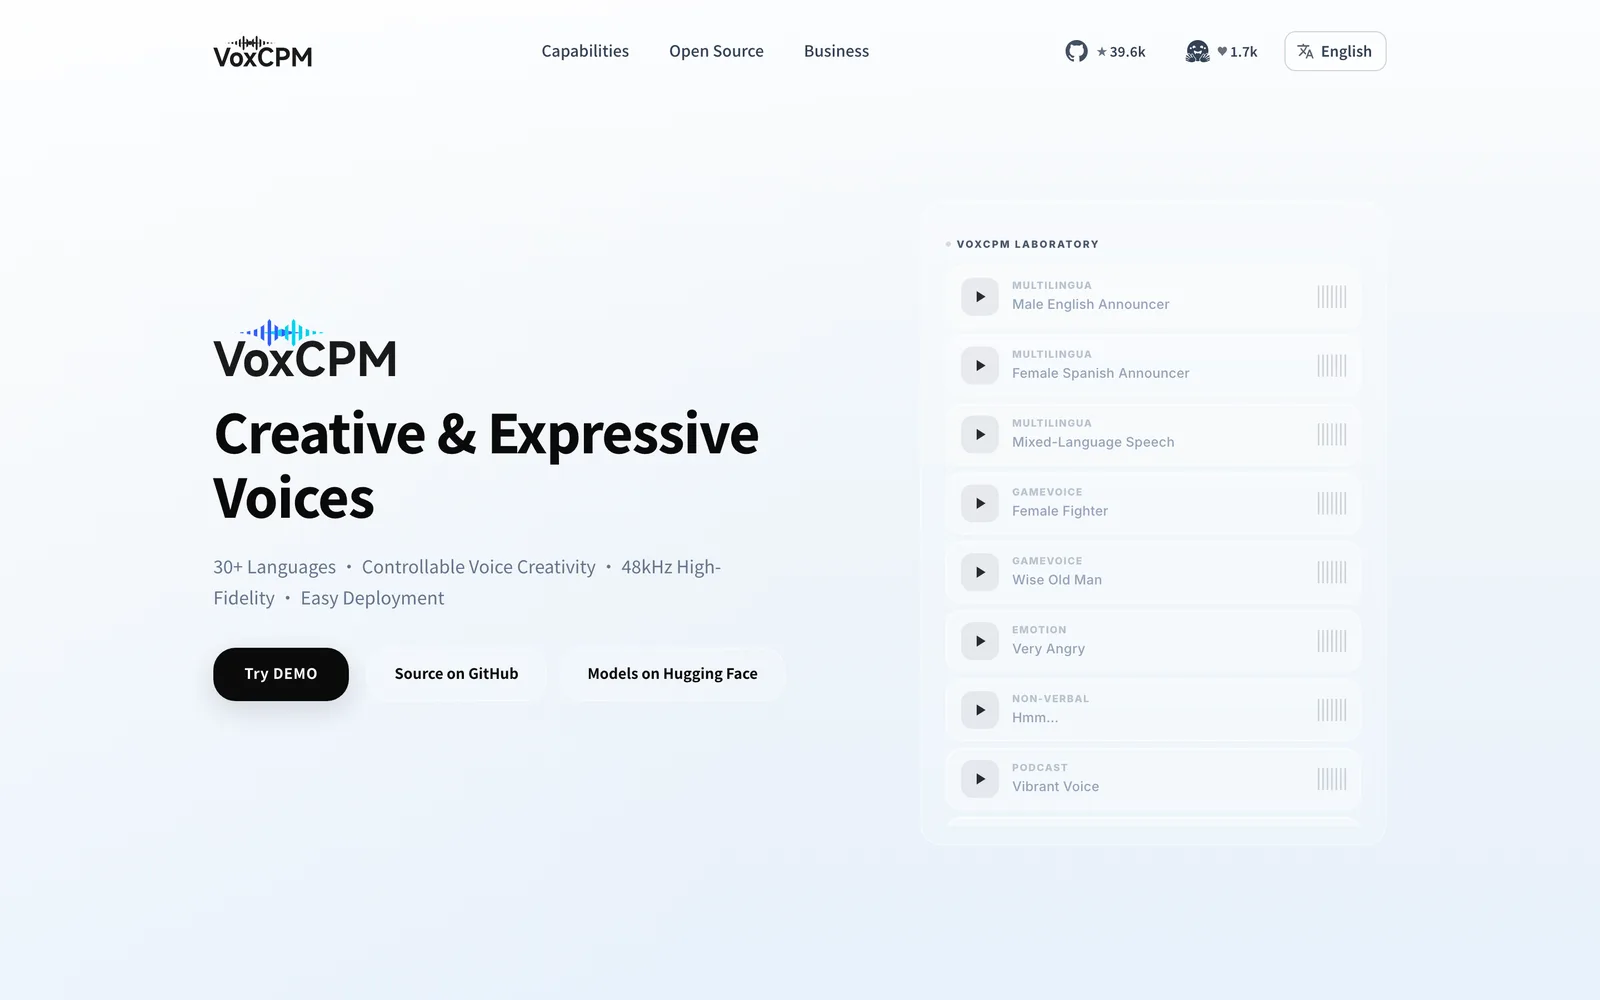
VoxCPM2 is an open-source Text-to-Speech (TTS) system by OpenBMB. It uses an end-to-end diffusion autoregressive architecture to directly generate continuous speech representations, bypassing discrete tokenization. The 2B-parameter model is built on the MiniCPM-4 backbone and trained on over 2 million hours of multilingual speech data, supporting 30 languages and multiple Chinese dialects (such as Sichuanese, Cantonese, and Wu). ### Key Capabilities - **Multilingual Synthesis**: Directly synthesize speech from text in any of the 30 supported languages without language tags. - **Voice Design**: Create new voices using only natural language descriptions (e.g., gender, age, tone, emotion, speed) with no reference audio required. - **Controllable Voice Cloning**: Clone a voice from a short reference clip and control emotion, speed, and delivery via style guidance while preserving the original timbre. - **Extreme Cloning**: Given a reference audio and its transcript, the model seamlessly continues from the reference, retaining timbre, rhythm, emotion, and stylistic details. - **48kHz High-Quality Output**: Accepts 16kHz reference audio and directly outputs studio-grade 48kHz audio via AudioVAE V2's asymmetric codec design, with built-in super-resolution and no external upsampler needed. - **Context-Aware Synthesis**: Automatically infers appropriate prosody and expressiveness from the text content. - **Real-Time Streaming Inference**: Achieves an RTF of ~0.3 on NVIDIA RTX 4090; accelerated with Nano-vLLM or vLLM-Omni, it drops to ~0.13, with an OpenAI-compatible API provided. ### Usage The project offers a Python API, CLI, and Web Demo. Requirements: Python ≥ 3.10 (<3.13), PyTorch ≥ 2.5.0, CUDA ≥ 12.0. Install via `pip install voxcpm`; model weights are available on Hugging Face or ModelScope. ### Target Audience Ideal for developers and researchers needing multilingual speech synthesis, custom voice design, or high-fidelity voice cloning. Code and weights are released under Apache-2.0, allowing free commercial use.
Key features
- Tokenizer-Free Architecture: Generates continuous speech representations directly via an end-to-end diffusion autoregressive architecture, skipping discrete tokenization.
- 30-Language Support: Supports 30 languages and multiple Chinese dialects. Synthesize speech directly from text without language tags.
- Natural Language Voice Design: Create entirely new voices using only text descriptions of gender, age, tone, etc., with no reference audio needed.
- Controllable Voice Cloning: Clone voices from short audio clips while controlling emotion, speed, and other styles, preserving the original timbre.
- Extreme Voice Cloning: Provide a reference audio and transcript, and the model seamlessly continues while retaining timbre, rhythm, emotion, and all details.
- 48kHz High-Quality Audio Output: Accepts 16kHz input and directly outputs 48kHz audio via AudioVAE V2's asymmetric codec.
- Context-Aware Synthesis: Automatically infers appropriate prosody and expressiveness based on text content.
- Real-Time Streaming Inference: RTF of ~0.3 on RTX 4090, dropping to ~0.13 with vLLM acceleration.
- Python API & CLI: Provides a pip package, Python API, and command-line tools.
- Apache-2.0 License: Code and model weights are fully open source and free for commercial use.
Releases
Notify me Initial · VoxCPM2
Q&A
- Which languages does VoxCPM2 support?AI-generated
- It supports 30 languages, including Arabic, Chinese, English, French, German, Japanese, Korean, Russian, and Spanish, as well as Chinese dialects such as Sichuanese, Cantonese, Wu, and Northeastern Mandarin.
- How do I design a new voice without providing reference audio?AI-generated
- When calling the generate method, place the natural language description in parentheses at the beginning of the text parameter, e.g., "(A young woman, gentle and sweet voice)Hello". The model will generate the corresponding voice based on the description.
- What environment dependencies are required to run VoxCPM2?AI-generated
- Requires Python ≥ 3.10 and < 3.13, PyTorch ≥ 2.5.0, and CUDA ≥ 12.0. Install via pip install voxcpm.
- Can VoxCPM2 be used commercially?AI-generated
- Yes. Both the code and model weights of VoxCPM2 are released under the Apache-2.0 license, allowing free commercial use.
- How fast is VoxCPM2 inference?AI-generated
- On an NVIDIA RTX 4090, the RTF is about 0.3. With Nano-vLLM or vLLM-Omni acceleration, the RTF can drop to approximately 0.13.
- What are the parameter count and training data scale of the model?AI-generated
- VoxCPM2 is a 2B-parameter model built on the MiniCPM-4 backbone, trained on over 2 million hours of multilingual speech data.
Bookmark
This product has no owner yet
It was listed by the platform or its author left. If it is your work, prove your relationship to become the owner.
Claim this productAlternatives


The product content on this page was translated by AI from the author's original.